AI Agent Memory Systems: A Complete Tutorial from Basics to Production Deployment
Memory systems are the defining feature of AI agents in 2026. This tutorial covers short-term memory, long-term storage, vector database integration, RAG architecture, and real-world deployment patterns.
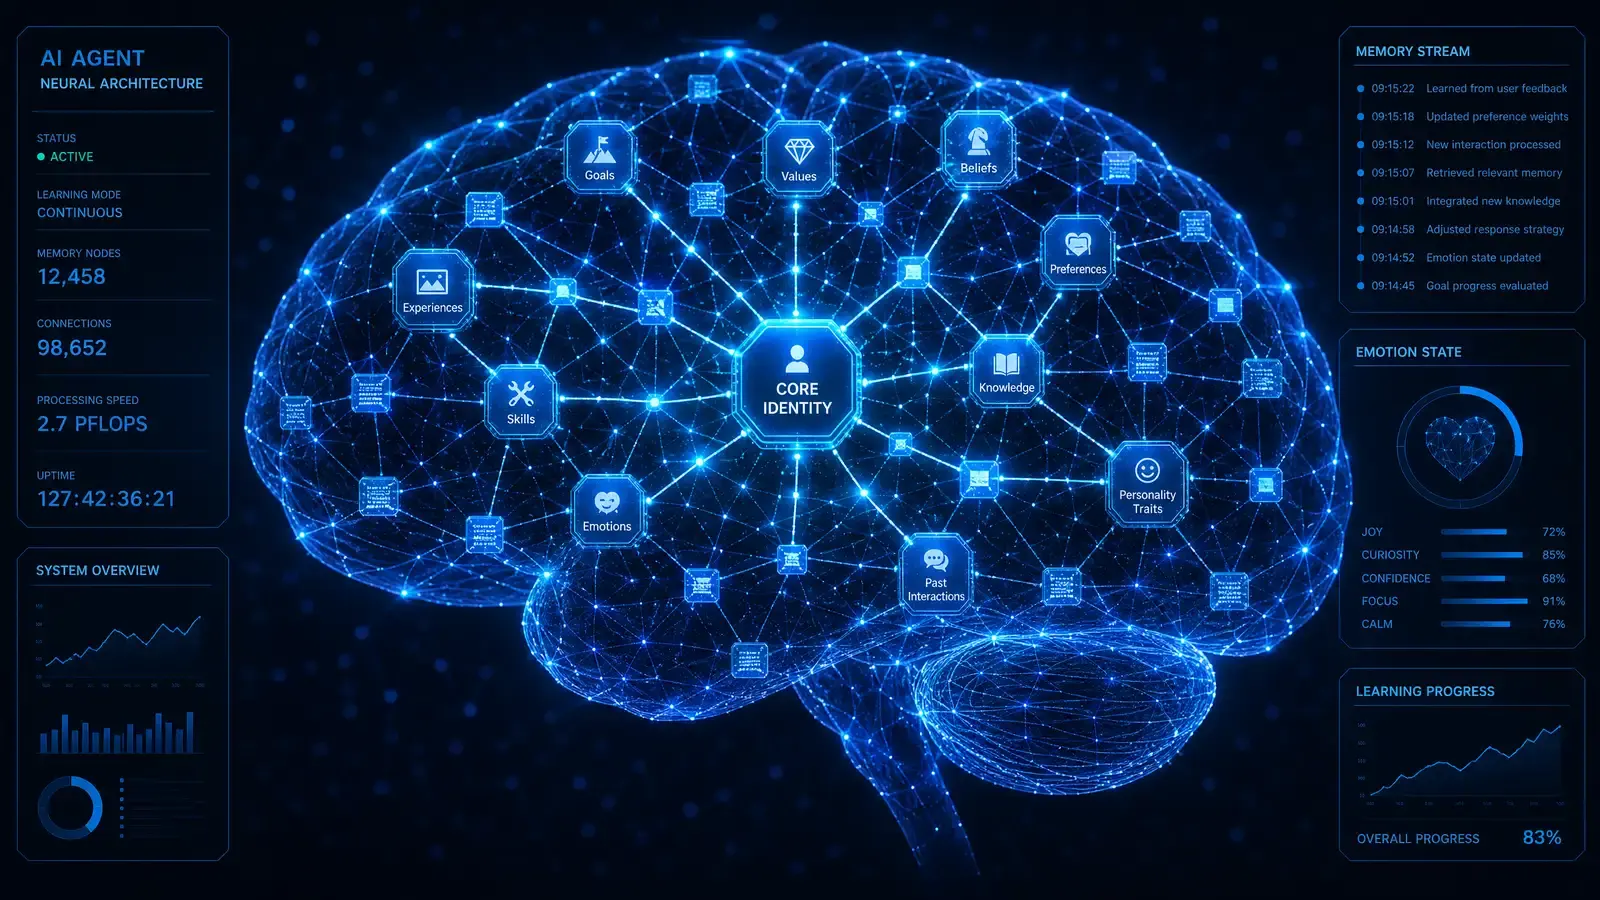
The biggest difference between an AI agent and a regular chatbot? Memory.
An AI model without memory treats every conversation like the first one — regardless of what you discussed five minutes ago, it starts from scratch. In 2026, memory systems for AI agents have moved from experimental features to core infrastructure. This tutorial takes you from basic concepts to production deployment.
Why AI Agents Need Memory
Think about working with a colleague who forgets every previous meeting. How much time would you spend re-explaining things? AI agents face the exact same problem.
Memory systems enable agents to:
- Remember user preferences and conversation history
- Accumulate knowledge across sessions
- Make better decisions based on past experience
- Deliver personalized responses
Without memory, an agent is just a sophisticated auto-reply system. With memory, it becomes a genuine “agent.”
Three Types of Memory
1. Short-Term Memory (Session Memory)
Short-term memory is the current conversation context. It’s the simplest form — pass the conversation history to the LLM so it knows “what we just talked about.”
from langchain_core.messages import HumanMessage, AIMessage

messages = [
    HumanMessage(content="I love Python's asyncio"),
    AIMessage(content="asyncio is indeed a powerful feature..."),
    HumanMessage(content="How do I handle concurrent tasks?"),
]
The limitation is obvious: LLMs have finite context windows. Long conversations exceed the limit, and older messages get truncated.
2. Mid-Term Memory (Summary Memory)
When conversations grow too long, you compress older exchanges into summaries that retain only key information:
from langchain_core.messages import SystemMessage

# Compress old conversation into a summary
summary = "User prefers Python asyncio, currently asking about concurrent task handling"
messages = [SystemMessage(content=summary)] + recent_messages
This approach balances context length with information retention and is the preferred pattern for most production environments.
3. Long-Term Memory (Persistent Memory)
Long-term memory is the real game-changer. It lets agents remember things across sessions — like a friend who actually knows you.
The implementation is typically a vector database combined with Retrieval-Augmented Generation (RAG):
from langchain_community.vectorstores import Chroma
from langchain_openai import OpenAIEmbeddings

# Create vector store
embeddings = OpenAIEmbeddings()
vectorstore = Chroma(
    collection_name="agent_memory",
    embedding_function=embeddings,
    persist_directory="./memory_db"
)

# Store a memory
vectorstore.add_texts(
    texts=["User prefers Python over JavaScript"],
    metadatas=[{"type": "preference", "timestamp": "2026-06-22"}]
)

# Retrieve relevant memories
relevant = vectorstore.similarity_search("Which programming language?", k=3)
Complete Memory Architecture
A production-grade agent memory system should include these layers:
- Working memory: Current conversation context (within LLM window limits)
- Summary buffer: Compressed summaries of recent conversations
- Vector memory store: Vector embeddings of all historical interactions
- Facts database: Structured user information (preferences, profiles)
User Input → [Retrieve Relevant Memories] → [Assemble Context] → LLM → [Store New Memory] → ResponseIn Practice: Building a Memory-Aware Agent with LangGraph
LangGraph provides the most complete agent memory solution:
from langgraph.checkpoint.memory import MemorySaver

# Create persistent checkpointer
memory = MemorySaver()

# Use in graph
app = graph.compile(checkpointer=memory)

# Each conversation carries a thread_id
config = {"configurable": {"thread_id": "user-123"}}
result = app.invoke({"messages": [HumanMessage(content="Hello")]}, config=config)
Now the agent remembers the user across sessions. The next request with the same thread_id automatically loads the previous conversation state.
Performance Considerations
Memory systems aren’t free. Each retrieval requires:
- Vector computation (embedding + similarity search)
- Context assembly (integrating multiple memories into a single prompt)
- LLM processing (longer context = higher token cost)
Recommended best practices:
- Set a memory retrieval cap (e.g., maximum 5 relevant memories)
- Use caching to reduce redundant embedding computations
- Periodically clean expired or low-value memories
- Assign “importance scores” to memories and prioritize high-score retrieval
How Major Frameworks Implement Memory
The three-layer model above maps onto features that agent frameworks now provide out of the box. Knowing what each offers can save you from building memory from scratch.
LangGraph: checkpoints and stores
The LangGraph memory guide separates memory by recall scope. Short-term memory is thread-scoped: it lives in the agent’s state and is persisted through checkpoints, so a conversation identified by a thread_id can be resumed later. That state can include messages as well as uploaded files, retrieved documents or generated artifacts. Long-term memory is stored across sessions in a store, organised by custom namespaces (for example, per user), so it can be shared across threads.
OpenAI Agents SDK: sessions
The Agents SDK sessions feature automatically keeps conversation history across agent runs. Before each run, the runner retrieves the session’s history and prepends it to the input; after the run, new items such as user input, responses and tool calls are stored. This covers short-term memory with very little code, but long-term memory, such as user preferences across sessions, is still up to you.
Anthropic’s memory tool
Anthropic’s memory tool takes a file-based approach. Claude can create, read, update and delete files in a memory directory that persists between sessions, and it checks that directory before starting a task. The tool runs client-side: Claude requests file operations and your application executes them against storage you control, such as a per-user directory or database keys. This supports “just-in-time” retrieval, where the agent reads only the notes it needs instead of loading everything into context.
Choosing an approach
| Need | Reasonable starting point |
|---|---|
| Resume a conversation | Framework checkpoints or sessions |
| Remember user preferences across sessions | A namespaced store or memory files per user |
| Search large amounts of past knowledge | A vector database with semantic retrieval |
| Full control over data location | Client-side storage, such as a memory tool you implement |
Privacy and Data Handling
Memory makes agents more useful, but it also means storing personal data. Good practice includes:
- Tell users what is remembered and give them a way to view and delete it.
- Scope memory per user so one user’s information can never be retrieved for another.
- Avoid storing secrets such as passwords, API keys or payment details in memory.
- Set retention limits and delete stale memories automatically.
- Check applicable law, such as data-protection rules, for where memory data is stored and how long it is kept.
Summary
AI agent memory systems are among the most practically valuable technologies of 2026. From simple conversation history to vector database-driven long-term memory, each layer makes agents smarter and more useful.
The key isn’t “add all memories.” It’s “provide the right memory at the right time.” A good memory system works like an excellent assistant — it knows what information you need and delivers it at just the right moment.
Sources
Reader Dispatches
No reader responses yet. Share your technical perspective below.
Related Posts
AI Agent Memory Management: How to Make Your AI Assistant Actually Remember Things in 2026
Most AI agents lose context between conversations because of poor memory architecture. This guide covers short-term, working, and long-term memory patterns with practical Python examples.
How to Build Your First Multi-Agent AI System with CrewAI in 2026
A step-by-step beginner's guide to building collaborative AI agents using CrewAI, the fastest-growing multi-agent framework of 2026.
OpenAI Agents SDK Tutorial: Build a Research Agent That Actually Works with Responses API and MCP
Learn how to build a practical research agent with OpenAI Agents SDK, Responses API, and Hosted MCP Tool. This guide focuses on architecture, approvals, and tool boundaries instead of toy demos.